Smart gating
Deciding in milliseconds whether a new piece of speech is worth an LLM call.
Benchmark for this version
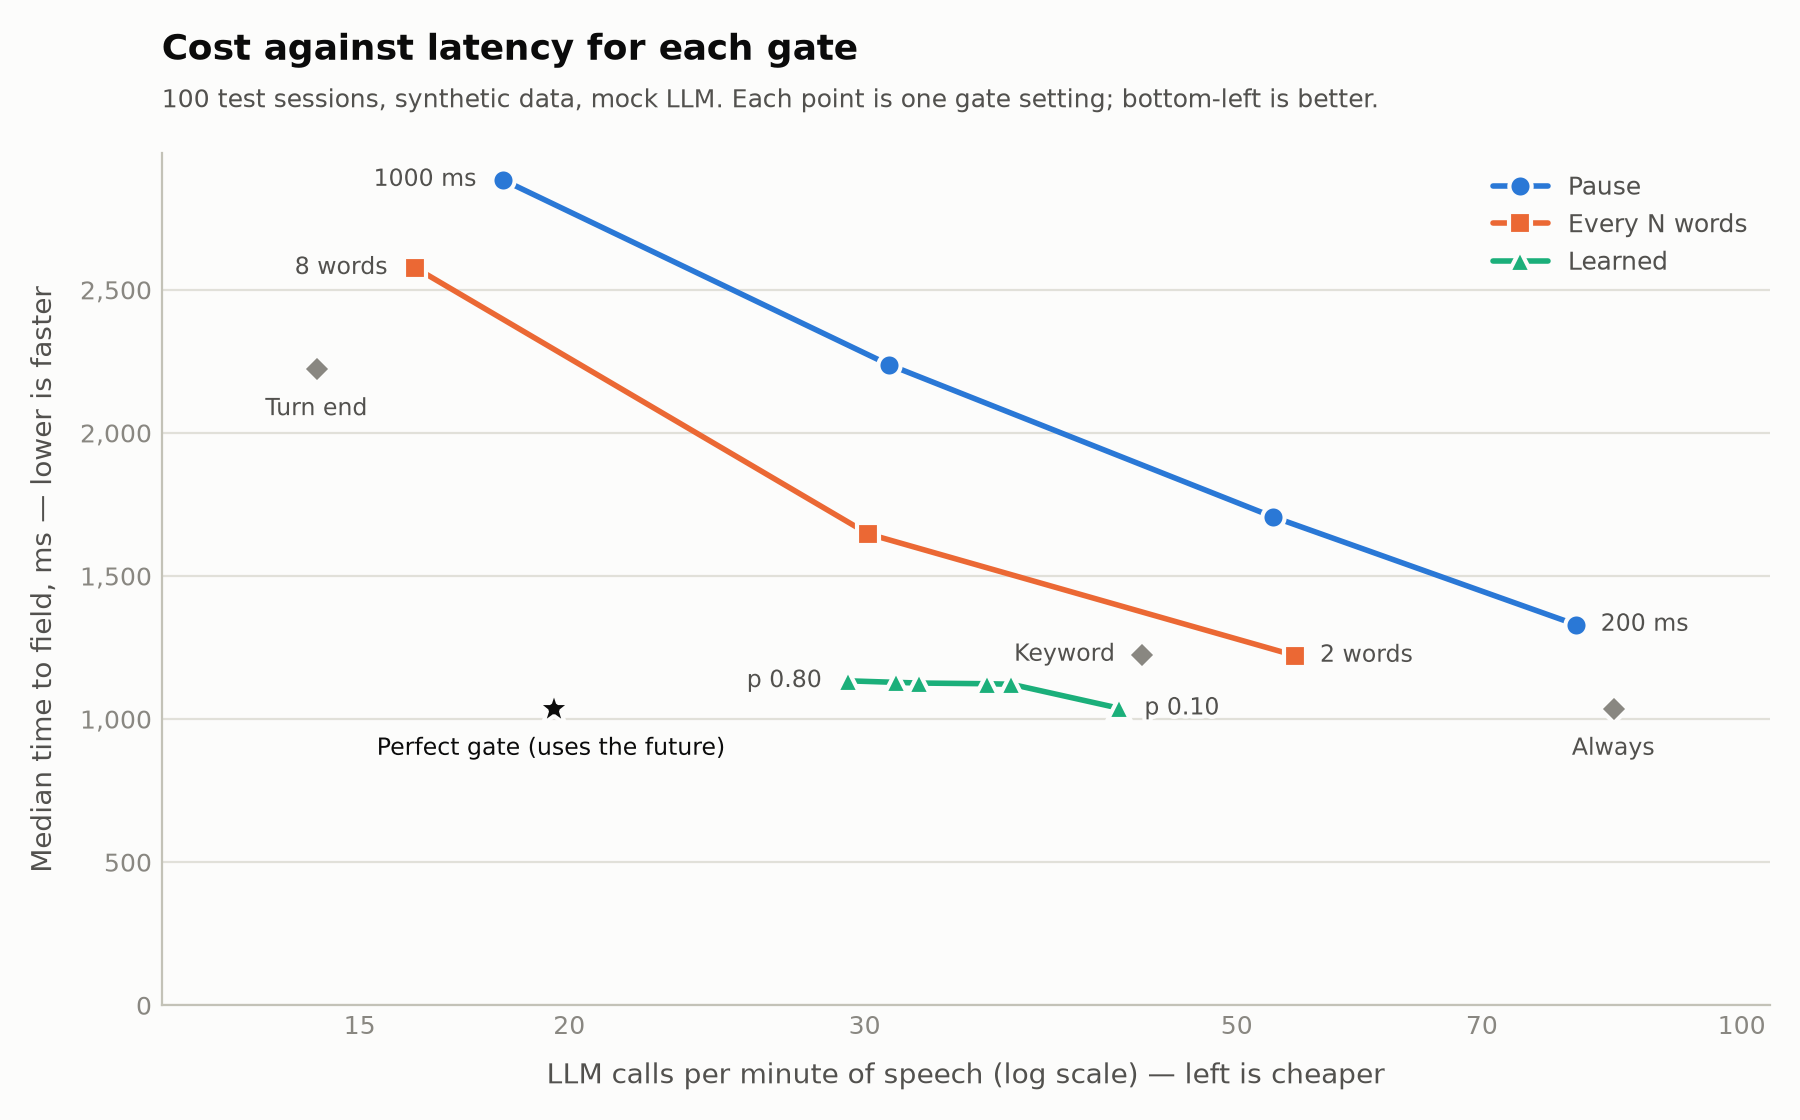
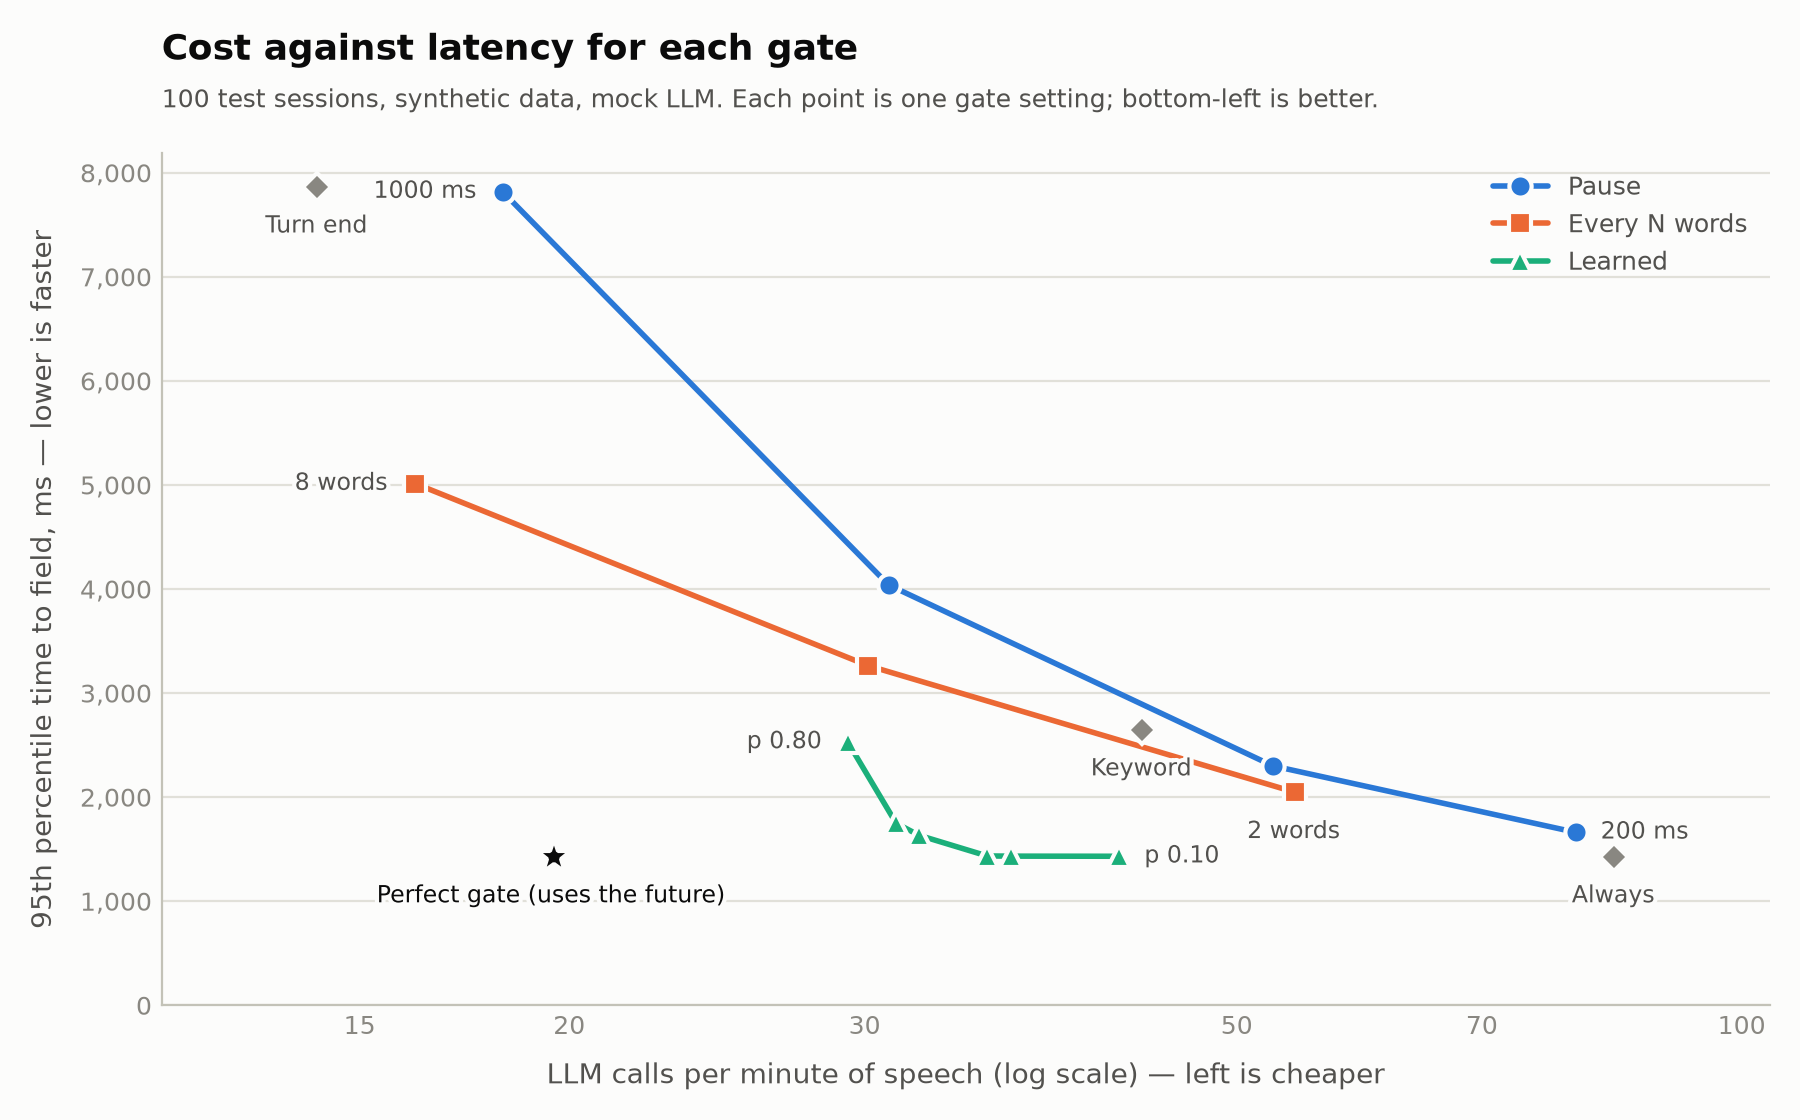
Synthetic data and a mock LLM: this shows what the harness produces, not a result. The live demo is not built yet.
Tail latency: 95th percentile chart · results.csv
Every gate, same test sessions
| Gate | Calls / min | × perfect | Precision | Recall | Gate delay p50 | Time to field p50 | p95 | Decision p95 |
|---|---|---|---|---|---|---|---|---|
| always | 84.0 | 4.29 | 0.20 | 1.00 | 0 | 1035 | 1430 | 0 |
| turn_end | 14.2 | 0.72 | 0.77 | 0.43 | 1140 | 2222 | 7867 | 0 |
| every_2_words | 54.2 | 2.77 | 0.32 | 0.90 | 0 | 1222 | 2047 | 23 |
| every_4_words | 30.1 | 1.54 | 0.54 | 0.50 | 495 | 1647 | 3264 | 25 |
| every_8_words | 16.2 | 0.83 | 0.84 | 0.29 | 1510 | 2577 | 5013 | 30 |
| pause_200ms | 79.6 | 4.07 | 0.22 | 1.00 | 251 | 1330 | 1662 | 1 |
| pause_400ms | 52.5 | 2.68 | 0.32 | 0.51 | 497 | 1707 | 2301 | 1 |
| pause_700ms | 31.0 | 1.58 | 0.49 | 0.00 | 1135 | 2239 | 4039 | 1 |
| pause_1000ms | 18.2 | 0.93 | 0.67 | 0.00 | 1775 | 2885 | 7819 | 1 |
| keyword+pause_700ms | 43.9 | 2.24 | 0.40 | 0.76 | 0 | 1226 | 2650 | 56 |
| learned_p0.10 | 42.6 | 2.17 | 0.42 | 0.99 | 0 | 1038 | 1432 | 104 |
| learned_p0.20 | 36.7 | 1.87 | 0.49 | 0.98 | 0 | 1122 | 1433 | 123 |
| learned_p0.35 | 35.5 | 1.81 | 0.51 | 0.99 | 0 | 1124 | 1435 | 107 |
| learned_p0.50 | 32.3 | 1.65 | 0.55 | 0.95 | 0 | 1126 | 1633 | 108 |
| learned_p0.65 | 31.3 | 1.60 | 0.57 | 0.94 | 0 | 1128 | 1750 | 92 |
| learned_p0.80 | 29.3 | 1.50 | 0.59 | 0.87 | 0 | 1134 | 2530 | 103 |
| perfect (oracle) | 19.6 | 1.00 | 1.00 | 1.00 | 0 | 1035 | 1430 | 0 |
Delays and time to field are in milliseconds; decision time is in microseconds. Recall counts changes the gate acted on within 500 ms.